追了一半还没追完的电视剧,
永远也不会知道结局了。
还剩29袋的G7速溶咖啡,
这辈子是喝不完了。
买了两年的添柏岚大黄靴,
只穿了两次。
新房还没住几天。
爱人的一身病还没治好。
老母亲的护照都办好好几年了却没出过国。
孩子仍未离开地球。
还没有去过南极,
感受孤独。
没有成为一名科学家,
也不是作家。
国足还未第二次打入世界杯。
台湾还未回到祖国怀抱。
所有这一切,
就此成为了我的专属遗憾。


追了一半还没追完的电视剧,
永远也不会知道结局了。
还剩29袋的G7速溶咖啡,
这辈子是喝不完了。
买了两年的添柏岚大黄靴,
只穿了两次。
新房还没住几天。
爱人的一身病还没治好。
老母亲的护照都办好好几年了却没出过国。
孩子仍未离开地球。
还没有去过南极,
感受孤独。
没有成为一名科学家,
也不是作家。
国足还未第二次打入世界杯。
台湾还未回到祖国怀抱。
所有这一切,
就此成为了我的专属遗憾。
一个很古老的软件,好像是Windows XP时期的,可以轻松删除Windows服务的小工具,现在依然可以用,目前最新的Windows 11和Windows Server 2022都是支持的。此版本为WinG汉化版,有需要的同学可以放心下载。
比较适合初级用户使用,当然使用如下命令也是可以的:
sc delete <服务名称>
下载次数:
软件介绍
SRVINSTW.EXE是一款专为Windows系统打造的服务管理工具。通过SRVINSTW.EXE,用户可以轻松的卸载掉一些不需要的Windows服务,减少空间占用,提高电脑的运行速度。SRVINSTW.EXE最新版支持安装缺失服务以及卸载无用服务功能,为管理日常系统服务带来便利。
使用方法
1、下载解压后,运行srvinstw.exe,然后选择安装服务或是卸载服务;
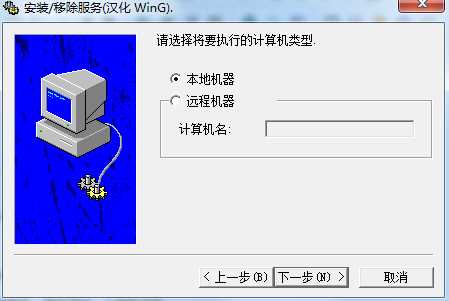
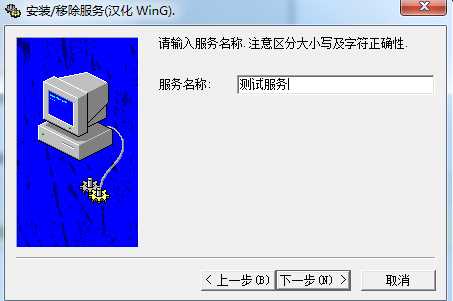
2、如果是安装服务,选择本地服务,然后添加一个服务名称
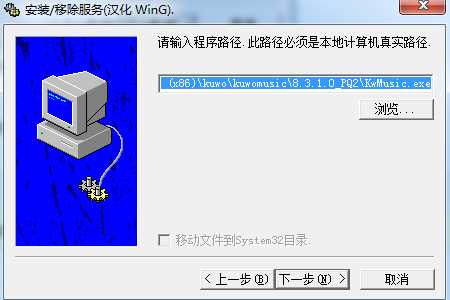
3、浏览到你要添加服务的程序,EXE文件哦;
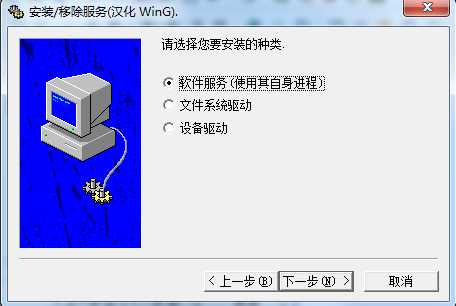
4、选择安装种类,一般选择软件服务就可以了!别的自己测试吧。
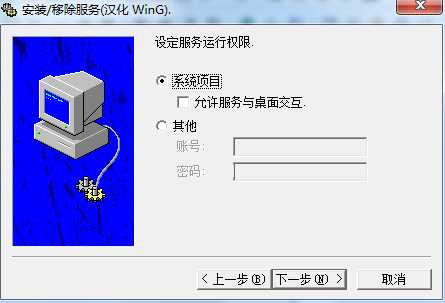
5、选择为系统项目;
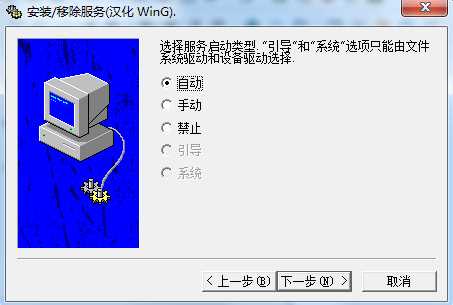
6、启动类型,相信大家都懂的,要开机运行就自动;
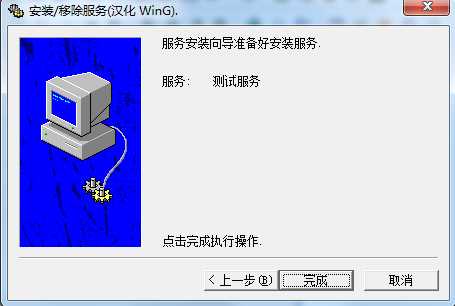
7、完成服务的添加了。
8、去系统中看一下,我们可以看到刚添加的服务;
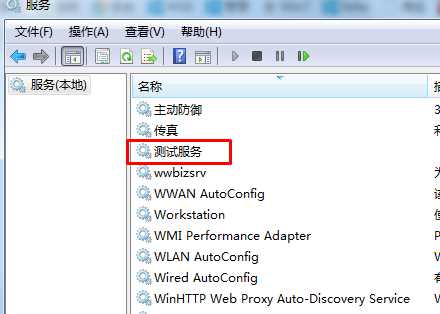
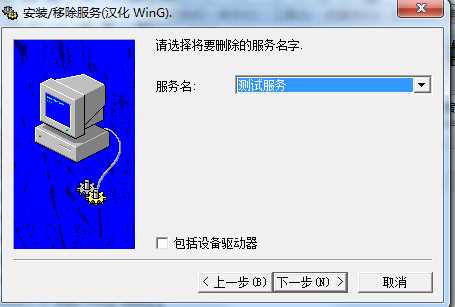
9、移除服务,选择你要移除的服务,千万不要移除了系统服务哦。
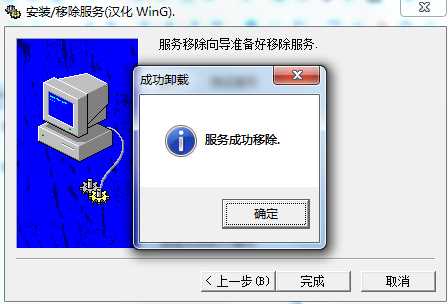
10、移除成功~~
总之srvinstw是一个操作简单傻瓜式的服务安装卸载工具。

来看看Vultr在2024年的优惠活动吧!
用Vultr得有十多年了,最近几年发现Vultr是越来越棒了,支持支付宝,而且在国内的访问速度也是越来越快。
如果你还在犹豫海外VPS选择哪家,现在就不要犹豫了,用Vultr准没错。而且现在在搞活动,优惠力度巨大无比,满足条件后赠送你300刀!!!以前我怎么就没有遇到呢!
https://www.vultr.com/?ref=9635902-9J
另外如果囊中羞涩,也可以使用如下链接薅羊毛,只不过羊毛少一些罢了,只有10美元。
https://www.vultr.com/?ref=7050304

最近某客户在测试SolarWinds的SEM模块,由于SEM模块目前还在新版本的变革之中,报表功能甚至直接下架,只能依靠羸弱的Web界面去生成报表,呈现的内容无法深度加工,无法满足客户汇总关键信息的需求。身为一个编程小白,为了能够拿下这一单,只能求助ChatGPT了。
这里我采用的是Sider,对国内用户非常友好,国际主流的AI基本都有了,只要本地网络足够稳定,就不会有任何卡顿,如果需要的同学可以点击以下链接注册,还可以额外赠送多次查询次数。
这个AI工具超好用,每天都有免费额度,写文章、总结长视频、画图等,都几秒搞定!快去下载Sider Chrome或Edge插件,薅羊毛!
https://sider.ai/invited?c=7e6ad196e0c3a5eea1d0bbc85e4fbd2c
接下来进入正文。
根据以上需求看起来还是很简单的,但最重要的是如何去匹配抓取单元格内的二级域名,观察其特征,然后再跟ChatGPT不断沟通确定最终的方案。
而解析次数就比较简单了,直接统计该二级域名重复的次数即可。
另外,站在客户的角度来思考问题,肯定是不希望增加自己工作量的,所以我们要替客户尽量简化该脚本的使用步骤,毕竟买了你一个产品,我还要去复杂的运行一个脚本来实现我的需求,搁谁也是不愿意的。
我所想到的办法是:
先跟ChatGPT(下面简称人工智障)说:
帮我用python写一个脚本,处理一个在zip压缩包中的csv文件(这个文件有点大,170000多行数据,目前是70多MB,未来会更大,所以你写出的脚本需要适应未来的变化,我不希望去分片处理,但是可以在内存中处理),我不想手动解压这个zip文件,我希望python脚本能够自己解压缩,然后处理里面的csv的文件。最终经过下面所要求的方式处理,输出一个xlsx的文件。
具体需求如下:
1.提取第L列第一行(ExtraneousInfo)和第AV列第一行(DestinationMachine)以下的数据,也就是从第二行开始提取。
2.L列的数据需要从右向左检索,在遇到第二个”.”或空格时则停止,只保留第二个”.”或空格右侧的字符。
以下为L列相关数据举例:
“Response: “NOERROR”, Flags: “DR”, cecom.oss-cn-beijing.aliyuncs.com”
“Response: “NOERROR”, Flags: “D”, gstatic.com”
我想要的数据为:
“aliyuncs.com”
“gstatic.com”
3.完成第二步的工作后,创建一个新的xlsx文件(具体在哪一步创建这个新的xlsx文件由您来决定),并在A列第一行写入“域名”,然后把第二步的内容从第二行开始导入其中。
4.开始处理xlsx文件中的A列,首先去重,然后在B列第一行命名为“查询次数”,将每一个域名重复出现的次数自动填充在B列的每一个域名对应行的后面。
5.将csv文件中的第AV列的数据传至xlsx文件的C列,C列第一行命名为“客户端IP地址”,并进行去重。
6.无论第4、5步如何处理,都要确保在原始的csv文件中他们的ExtraneousInfo和DestinationMachine都能对应上。
我不希望手动指定zip文件的路径,我希望运行该脚本,该脚本能够自动的读取当前目录下的zip文件并进行处理,然后自动的输出一个名为“DNS查询统计-服务器:xxxxxxx”的xlsx文件,xxxxxxx请读取csv文件E列(DetectionIP)第二行的数据进行替换。
人工智障自动调用了GPT-4o mini来应对
可以根据你的需求编写一个完整的Python脚本。这个脚本会自动解压当前目录下的zip文件,读取CSV文件并完成你所要求的处理。以下是满足你需求的代码示例:
import pandas as pd
import zipfile
import os
import re

# 获取当前目录下的zip文件路径
current_dir = os.getcwd()
zip_files = [f for f in os.listdir(current_dir) if f.endswith('.zip')]

# 检查是否存在zip文件
if not zip_files:
    raise FileNotFoundError("当前目录下没有找到zip文件")
elif len(zip_files) > 1:
    raise RuntimeError("当前目录下存在多个zip文件,请确保只有一个zip文件")

zip_file_path = os.path.join(current_dir, zip_files[0])

# 解压缩zip文件并读取CSV
with zipfile.ZipFile(zip_file_path, 'r') as zip_ref:
    # 获取zip中的文件名
    file_names = zip_ref.namelist()
    csv_file_name = file_names[0]

    # 读取CSV文件,设置low_memory=False
    with zip_ref.open(csv_file_name) as csv_file:
        df = pd.read_csv(csv_file, low_memory=False)

# 获取E列第二行的数据用于生成文件名
server_ip = df.iloc[1, df.columns.get_loc('DetectionIP')]

# 需求1: 提取L列和AV列的数据
extraneous_info = df.iloc[1:, df.columns.get_loc('ExtraneousInfo')]
destination_machine = df.iloc[1:, df.columns.get_loc('DestinationMachine')]

# 需求2: 处理L列数据
def extract_domain(info):
    # 从右向左检索第二个"."或者空格
    match = re.findall(r'(\.| )[^\. ]+$', info)
    if len(match) > 1:
        return info.split(".")[-2] + '.' + info.split(".")[-1]
    return info

# 提取域名
domains = extraneous_info.apply(extract_domain)

# 创建DataFrame以存储域名
domain_df = pd.DataFrame({'域名': domains})

# 需求4: 去重并统计查询次数
domain_counts = domain_df['域名'].value_counts().reset_index()
domain_counts.columns = ['域名', '查询次数']

# 需求5: 处理DestinationMachine列并去重
unique_ips = destination_machine.drop_duplicates().reset_index(drop=True)
unique_ips.name = '客户端IP地址'

# 将数据合并到最终的DataFrame
final_df = pd.merge(domain_counts, unique_ips.to_frame(), left_index=True, right_index=True, how='left')

# 生成输出文件名
output_xlsx_path = os.path.join(current_dir, f'DNS查询统计-服务器:{server_ip}.xlsx')

# 写入输出xlsx文件
with pd.ExcelWriter(output_xlsx_path) as writer:
    final_df.to_excel(writer, index=False)

print(f'处理完成,结果保存在 {output_xlsx_path}')
代码说明:
- 自动读取zip文件:脚本会查找当前目录下的所有zip文件,并选择第一个进行处理。
- 解压CSV文件:通过
zipfile库自动解压并读取CSV文件。- 数据处理:
- 从
ExtraneousInfo列提取信息并通过正则表达式来获取域名。- 统计重复的域名并生成一个新的DataFrame。
- 将
DestinationMachine的唯一IP地址添加到输出中。- 创建输出文件:生成的Excel文件命名为
DNS查询统计-服务器:xxxxxxx.xlsx,其中xxxxxxx为DetectionIP字段的第二行数据。- 保存结果:使用
pandas的ExcelWriter将结果写入新创建的Excel文件中。注意事项:
- 确保你的环境中已安装必要的库:
pandas和openpyxl。你可以通过以下命令安装:pip install pandas openpyxl希望这个脚本能够满足你的需求!如果有任何问题或者需要进一步调整,请告诉我。
看起来还算可以,至少脚本主体出来了,上VSCode开始调试脚本,调试时发现二级域名提取的不对,点一点人工智障:
注意我关于L列的要求,请继续修改
以下为L列相关数据举例: “Response: “NOERROR”, Flags: “DR”, cecom.oss-cn-beijing.aliyuncs.com” “Response: “NOERROR”, Flags: “D”, gstatic.com” 我想要的数据为: “aliyuncs.com” “gstatic.com”
回复还挺快,立马做出了修改:
根据你的要求,我将修改代码以提取L列中的域名,确保只获取最后一个点(
.)后面的部分。以下是更新后的代码示例:import pandas as pd import zipfile import os import re # 获取当前目录下的zip文件路径 current_dir = os.getcwd() zip_files = [f for f in os.listdir(current_dir) if f.endswith('.zip')] # 检查是否存在zip文件 if not zip_files: raise FileNotFoundError("当前目录下没有找到zip文件") elif len(zip_files) > 1: raise RuntimeError("当前目录下存在多个zip文件,请确保只有一个zip文件") zip_file_path = os.path.join(current_dir, zip_files[0]) # 解压缩zip文件并读取CSV with zipfile.ZipFile(zip_file_path, 'r') as zip_ref: # 获取zip中的文件名 file_names = zip_ref.namelist() csv_file_name = file_names[0] # 读取CSV文件,设置low_memory=False with zip_ref.open(csv_file_name) as csv_file: df = pd.read_csv(csv_file, low_memory=False) # 获取E列第二行的数据用于生成文件名 server_ip = df.iloc[1, df.columns.get_loc('DetectionIP')] # 需求1: 提取L列和AV列的数据 extraneous_info = df.iloc[1:, df.columns.get_loc('ExtraneousInfo')] destination_machine = df.iloc[1:, df.columns.get_loc('DestinationMachine')] # 需求2: 处理L列数据,提取最后一个点后的域名 def extract_domain(info): # 使用正则表达式提取最后一个点后的部分 match = re.search(r'([^.]+\.[^.]+)$', info) return match.group(0) if match else None # 提取域名 domains = extraneous_info.apply(extract_domain) # 创建DataFrame以存储域名 domain_df = pd.DataFrame({'域名': domains}) # 需求4: 去重并统计查询次数 domain_counts = domain_df['域名'].value_counts().reset_index() domain_counts.columns = ['域名', '查询次数'] # 需求5: 处理DestinationMachine列并去重 unique_ips = destination_machine.drop_duplicates().reset_index(drop=True) unique_ips.name = '客户端IP地址' # 将数据合并到最终的DataFrame final_df = pd.merge(domain_counts, unique_ips.to_frame(), left_index=True, right_index=True, how='left') # 生成输出文件名 output_xlsx_path = os.path.join(current_dir, f'DNS查询统计-服务器:{server_ip}.xlsx') # 写入输出xlsx文件 with pd.ExcelWriter(output_xlsx_path) as writer: final_df.to_excel(writer, index=False) print(f'处理完成,结果保存在 {output_xlsx_path}')代码修改说明:
- 提取域名:在
extract_domain函数中,使用正则表达式r'([^.]+\.[^.]+)$'来匹配最后一个点后的部分,确保只提取域名的后缀部分。- 输出格式:最终的DataFrame将包含“域名”、“查询次数”和“客户端IP地址”三列,符合你的要求。
注意事项:
- 确保你的环境中已安装必要的库:
pandas和openpyxl。如果有其他需求或进一步的修改,请告诉我!
还是不行,看来得跟人工智障好好唠唠了。
使用你的脚本,对于以下L列单元格的文本,处理的结果是什么? Response: “NOERROR”, Flags: “DR”, app-analytics-services.com
人工智障挺着胸脯说道:
根据你提供的L列单元格文本“Response: “NOERROR”, Flags: “DR”, app-analytics-services.com”,使用我之前提供的脚本处理后,提取的结果将是:
域名:
analytics-services.com处理过程:
- 正则表达式
r'([^.]+\.[^.]+)$'会匹配最后一个点后的部分。- 在这个例子中,
app-analytics-services.com的最后一个点后是analytics-services.com。因此,最终的结果会在输出的Excel文件中显示为:
域名 查询次数 客户端IP地址 analytics-services.com 179267 XXX.XXX.XXX.XXX 如果你有其他问题或需要进一步的帮助,请告诉我!
还挺硬气,继续质问它:
那为何我在执行的时候不是这样的呢?而是没有任何处理的输出到了xlsx文件中
人工智障不紧不慢的补充道:
如果在执行脚本时没有任何处理的输出到xlsx文件,可能有几个原因。以下是几种可能性以及相应的解决方法:
- 数据未正确读取:
- 确保zip文件中的CSV文件格式正常,并且L列(
ExtraneousInfo)和其他列存在。- 检查是否存在任何空值或缺失值,可能导致后续处理结果为空。
- 正则表达式未匹配:
- 如果文本格式不完全符合预期(例如,前面有多余的空格或换行),正则表达式可能无法正确匹配。
- 可以通过在
extract_domain函数中输出调试信息,查看更多的文本数据,并检查正则表达式是否能正常匹配。- 文件路径和权限问题:
- 确保脚本的工作目录正确,并且可写权限正常。
- 检查输出路径是否有权限写入文件。
- DataFrame为空:
- 在执行到生成输出的步骤时,可以在输出前打印调试信息,例如
print(final_df),确认final_df是否包含数据。调试步骤:
- 加入打印调试信息:
在关键步骤前加上打印信息,例如:print("读取到的数据:") print(df.head()) print("提取的域名:") print(domains.head()) print("最终数据:") print(final_df)- 检查列名:
确保CSV文件中的列名确实为DetectionIP、ExtraneousInfo和DestinationMachine,避免大小写或额外空格导致的列名不匹配。- 单独测试提取函数:
可以单独测试extract_domain函数,确认它能处理你提供的样本数据。如果你仍然遇到问题,分享具体的错误信息或输出,我将更能帮助你找到解决方案!
单独打磨这个正则表达式函数就按下不表了,来来回回几个回合总算找到了病根,并且完美解决。
这次正确了,那请根据这次修改,重新写之前的脚本吧
然后,人工智障开始犯智障了。。。。
当然可以!以下是完整的脚本,包含更新后的
extract_domain函数以及测试样本数据部分:import re def extract_domain(text): # 使用正则表达式提取域名 match = re.search(r'([a-zA-Z0-9\-]+\.[a-zA-Z]{2,})', text) if match: return match.group(0) return None # 测试样本数据 test_cases = [ 'Response: "NOERROR", Flags: "DR", app-analytics-services.com', 'Response: "ERROR", Flags: "DR", example.co.uk', 'Some other text, no domain here', 'Response: "NOERROR", Flags: "DR", another-example.org' ] # 运行测试 for case in test_cases: result = extract_domain(case) print(f'输入: "{case}" => 提取的域名: {result}')说明:
- extract_domain 函数利用正则表达式提取域名。
- test_cases 列表中包含多个测试输入,用于验证函数的正确性。
- 最后,通过循环遍历测试样本,输出提取的结果。
你可以将这个脚本复制到你自己的Python环境中运行,应该会得到正确的域名提取结果。如果你有其他需求或问题,请告诉我!
把人工智障带回主线。
我的意思是把 def extract_domain(text): # 使用正则表达式提取域名 match = re.search(r'([a-zA-Z0-9\-]+\.[a-zA-Z]{2,})’, text) if match: return match.group(0) return None 这部分代码加入到我引用文本中提及的脚本中去,因为我不懂python,我不会修改。
根据你的要求,我将修改代码以提取L列中的域名,确保只获取最后一个点(`.`)后面的部分。以下是更新后的代码示例: “`python import pandas as pd import zipfile import os import re # 获取当前目录下的zip文件路径 current_dir = os.getcwd() zip_files = [f for f in os.listdir(current_dir) if f.endswith(‘.zip’)] # 检查是否存在zip文件 if not zip_files: raise FileNotFoundError(“当前目录下没有找到zip文件”) elif len(zip_files) > 1: raise RuntimeError(“当前目录下存在多个zip文件,请确保只有一个zip文件”) zip_file_path = os.path.join(current_dir, zip_files[0]) # 解压缩zip文件并读取CSV with zipfile.ZipFile(zip_file_path, ‘r’) as zip_ref: # 获取zip中的文件名 file_names = zip_ref.namelist() csv_file_name = file_names[0] # 读取CSV文件,设置low_memory=False with zip_ref.open(csv_file_name) as csv_file: df = pd.read_csv(csv_file, low_memory=False) # 获取E列第二行的数据用于生成文件名 server_ip = df.iloc[1, df.columns.get_loc(‘DetectionIP’)] # 需求1: 提取L列和AV列的数据 extraneous_info = df.iloc[1:, df.columns.get_loc(‘ExtraneousInfo’)] destination_machine = df.iloc[1:, df.columns.get_loc(‘DestinationMachine’)] # 需求2: 处理L列数据,提取最后一个点后的域名 def extract_domain(info): # 使用正则表达式提取最后一个点后的部分 match = re.search(r'([^.]+\.[^.]+)$’, info) return match.group(0) if match else None # 提取域名 domains = extraneous_info.apply(extract_domain) # 创建DataFrame以存储域名 domain_df = pd.DataFrame({‘域名’: domains}) # 需求4: 去重并统计查询次数 domain_counts = domain_df[‘域名’].value_counts().reset_index() domain_counts.columns = [‘域名’, ‘查询次数’] # 需求5: 处理DestinationMachine列并去重 unique_ips = destination_machine.drop_duplicates().reset_index(drop=True) unique_ips.name = ‘客户端IP地址’ # 将数据合并到最终的DataFrame final_df = pd.merge(domain_counts, unique_ips.to_frame(), left_index=True, right_index=True, how=’left’) # 生成输出文件名 output_xlsx_path = os.path.join(current_dir, f’DNS查询统计-服务器:{server_ip}.xlsx’) # 写入输出xlsx文件 with pd.ExcelWriter(output_xlsx_path) as writer: final_df.to_excel(writer, index=False) print(f’处理完成,结果保存在 {output_xlsx_path}’) “` ### 代码修改说明: 1. **提取域名**:在`extract_domain`函数中,使用正则表达式`r'([^.]+\.[^.]+)$’`来匹配最后一个点后的部分,确保只提取域名的后缀部分。 2. **输出格式**:最终的DataFrame将包含“域名”、“查询次数”和“客户端IP地址”三列,符合你的要求。 ### 注意事项: – 确保你的环境中已安装必要的库:`pandas` 和 `openpyxl`。 如果有其他需求或进一步的修改,请告诉我!
人工智障老老实实又重新写了一遍:
好的!我已经将你提供的代码与之前的
extract_domain函数结合在一起,确保提取 L 列中的域名。以下是更新后的完整脚本:import pandas as pd import zipfile import os import re # 获取当前目录下的zip文件路径 current_dir = os.getcwd() zip_files = [f for f in os.listdir(current_dir) if f.endswith('.zip')] # 检查是否存在zip文件 if not zip_files: raise FileNotFoundError("当前目录下没有找到zip文件") elif len(zip_files) > 1: raise RuntimeError("当前目录下存在多个zip文件,请确保只有一个zip文件") zip_file_path = os.path.join(current_dir, zip_files[0]) # 解压缩zip文件并读取CSV with zipfile.ZipFile(zip_file_path, 'r') as zip_ref: # 获取zip中的文件名 file_names = zip_ref.namelist() csv_file_name = file_names[0] # 读取CSV文件,设置low_memory=False with zip_ref.open(csv_file_name) as csv_file: df = pd.read_csv(csv_file, low_memory=False) # 获取E列第二行的数据用于生成文件名 server_ip = df.iloc[1, df.columns.get_loc('DetectionIP')] # 需求1: 提取L列和AV列的数据 extraneous_info = df.iloc[1:, df.columns.get_loc('ExtraneousInfo')] destination_machine = df.iloc[1:, df.columns.get_loc('DestinationMachine')] # 需求2: 处理L列数据,提取最后一个点后的域名 def extract_domain(info): # 使用正则表达式提取域名 match = re.search(r'([a-zA-Z0-9\-]+\.[a-zA-Z]{2,})', info) return match.group(0) if match else None # 提取域名 domains = extraneous_info.apply(extract_domain) # 创建DataFrame以存储域名 domain_df = pd.DataFrame({'域名': domains}) # 需求4: 去重并统计查询次数 domain_counts = domain_df['域名'].value_counts().reset_index() domain_counts.columns = ['域名', '查询次数'] # 需求5: 处理DestinationMachine列并去重 unique_ips = destination_machine.drop_duplicates().reset_index(drop=True) unique_ips.name = '客户端IP地址' # 将数据合并到最终的DataFrame final_df = pd.merge(domain_counts, unique_ips.to_frame(), left_index=True, right_index=True, how='left') # 生成输出文件名 output_xlsx_path = os.path.join(current_dir, f'DNS查询统计-服务器:{server_ip}.xlsx') # 写入输出xlsx文件 with pd.ExcelWriter(output_xlsx_path) as writer: final_df.to_excel(writer, index=False) print(f'处理完成,结果保存在 {output_xlsx_path}')代码说明:
- extract_domain 函数:使用正则表达式提取域名,确保只获取有效的域名格式。
- 数据处理:从 CSV 文件中提取数据并处理 L 列,提取域名。
- 输出结果:将提取的域名和相关信息写入 Excel 文件。
注意事项:
- 确保在运行此脚本之前,已安装
pandas和openpyxl库。- 该脚本会在当前工作目录下查找 ZIP 文件并处理其中的 CSV 文件。
如果你有其他问题或需要进一步的修改,请告诉我!
接下来还是有问题,来来回回又是几个回合,由于IP地址客户端的问题实在难以解决,客户也不是很关心该列,所以干脆让人工智障去掉算求子。最终,人工智障总算给我了最终的版本,完美,拿代码走人:
以下是修改后的代码,去掉了客户端IP列的处理和输出:
import pandas as pd
import zipfile
import os
import re

# 获取当前目录下的zip文件路径
current_dir = os.getcwd()
zip_files = [f for f in os.listdir(current_dir) if f.endswith('.zip')]

# 检查是否存在zip文件
if not zip_files:
    raise FileNotFoundError("当前目录下没有找到zip文件")
elif len(zip_files) > 1:
    raise RuntimeError("当前目录下存在多个zip文件,请确保只有一个zip文件")

zip_file_path = os.path.join(current_dir, zip_files[0])

# 解压缩zip文件并读取CSV
with zipfile.ZipFile(zip_file_path, 'r') as zip_ref:
    # 获取zip中的文件名
    file_names = zip_ref.namelist()
    csv_file_name = file_names[0]

    # 读取CSV文件,设置low_memory=False
    with zip_ref.open(csv_file_name) as csv_file:
        df = pd.read_csv(csv_file, low_memory=False)

# 获取E列第二行的数据用于生成文件名
server_ip = df.iloc[1, df.columns.get_loc('DetectionIP')]

# 需求1: 提取L列的数据
extraneous_info = df.iloc[1:, df.columns.get_loc('ExtraneousInfo')]

# 需求2: 处理L列数据,提取二级域名
def extract_second_level_domain(info):
    # 使用正则表达式从 DNS 响应日志中提取域名部分
    match = re.search(r'(?<=,\s)[\w.-]+\.[\w.-]+', info)
    if match:
        domain_parts = match.group(0).rsplit('.', 2)  # 分割域名成部分
        if len(domain_parts) >= 2:
            return f"{domain_parts[-2]}.{domain_parts[-1]}"  # 返回二级域名
    return None

# 提取二级域名
second_level_domains = extraneous_info.apply(extract_second_level_domain)

# 创建DataFrame以存储二级域名
domain_df = pd.DataFrame({'二级域名': second_level_domains})

# 需求4: 去重并统计查询次数
domain_counts = domain_df['二级域名'].value_counts().reset_index()
domain_counts.columns = ['二级域名', '查询次数']

# 生成输出文件名
output_xlsx_path = os.path.join(current_dir, f'DNS查询统计-服务器:{server_ip}.xlsx')

# 写入输出xlsx文件
with pd.ExcelWriter(output_xlsx_path) as writer:
    domain_counts.to_excel(writer, index=False)

print(f'处理完成,结果保存在 {output_xlsx_path}')
修改说明:
- 去掉客户端IP的处理:删除了与客户端IP相关的所有代码,包括提取、去重和合并步骤。
- 简化最终输出:只输出二级域名和查询次数的统计结果。
运行这段代码将只生成包含二级域名和查询次数的Excel文件。如果还有其他需求,请告诉我!
好了,脚本在手,调试一切OK,接下来就进行封装转exe了,这个就极为简单了,要确保开发环境安装pyinstaller,然后只需要一条命令就可以搞定,另外我也贴心的给exe文件加了一个ico,美美哒:
pyinstaller –onefile –nowindowed –icon=”E:\Python\Lib\site-packages_pyinstaller_hooks_contrib\terminal.ico” report_post-processing.py
至此,完成。
总结
跟人工智障的沟通,一定要事无巨细,当然有所遗漏也可以在后面补充,但如果token数量(沟通次数)非常紧张的话,那就必须要仔细打磨你想问的问题了。
如果人工智障跑偏了实在带不回来了,也没关系,重新建立一个新的会话,重新唠即可。
最后,有人工智障,真好。

Horizontal Scaling and Application Tiering for High Availability, Security, and Performance
Refer: https://documentation.solarwinds.com/en/success_center/servu/content/servu_documentation.htm
Serv-U is a high-performance secure file transfer server for Windows and Linux. It supports FTP, FTPS (SSL/TLS), SFTP (SSH), HTTP, and HTTPS connections, and includes optimized interfaces for web browsers and mobile devices (e.g., iPad, iPhone, BlackBerry, Android, Microsoft Windows Mobile, and Kindle Fire).
To support stringent redundancy, security, and performance requirements Serv-U supports both multi-tier and high availability architectures. This document describes Serv-U’s support for these distributed architectures and their relative advantages and disadvantages.
A multi-tier Serv-U / Serv-U Gateway deployment allows you to meet a common managed file transfer requirement: “never store data at rest in a DMZ.”
Serv-U Gateway safely proxies incoming connections from the Internet to your Serv-U server without opening any connections from the Internet or your DMZ segment into your trusted network.
The File Sharing module of Serv-U currently does not support High Availability environments. High Availability is designed for file transfers only.
Both the core Serv-U server and Serv-U Gateway can be deployed in “N+1” configurations to achieve high availability through horizontal scaling. This allows you to avoid single points of failure or scale up to meet your needs.
This section contains the minimum hardware requirements that need to be met, so that a given number of simultaneous transfers can be handled through the different protocols.
The provided data refer to single-instance Serv-U installations. For example, a single-instance installation can handle 500 simultaneous transfers through FTP with the given hardware. If you expect to have 1000 simultaneous transfers, it is recommended that you install 2 Serv-U instances, each of them meeting the requirements needed to handle 500 simultaneous transfers.
If the load is higher than expected for a given configuration, Serv-U remains functional, but the transfer rates will be diminished, and the user interface becomes less responsive.
| NUMBER OF SIMULTANEOUS TRANSFERS PER PROTOCOL | FTP (UNCOMPRESSED **), HTTP | ENCRYPTED (HTTPS, SFTP) |
| 10 | 512 MB RAM 7200 RPM HDD 2 core CPU * | 1 GB RAM 7200 RPM HDD 4 core CPU* |
| 25 | 1 GB RAM 7200 RPM HDD 2 core CPU * | 2 GB RAM 7200 RPM HDD 4 core CPU* |
| 50 | 2 GB RAM 10000 RPM HDD 4 core CPU* | 4 GB RAM 10000 RPM HDD 4+ core CPU* |
| 100 | 4 GB RAM 2x 10000 RPM HDD (RAID) 4 core CPU* | Multiple instances of Serv-U (2x) |
| 200 | 4+ GB RAM SSD HDD or 2x 10000 RPM HDD 4+ core CPU* | Multiple instances of Serv-U (4x) |
| 500 | 8+ GB RAM SSD HDD or 2x 15000 HDD (RAID) 8+ core CPU* | Please contact SolarWinds to define the requirements for your environment. |
| 1000 | Multiple instances of Serv-U (2x) | Please contact SolarWinds to define the requirements for your environment. |
* Using CPU with higher performance per core has significantly better impact on performance than increasing the number of CPU cores, therefore it is recommended that you use CPUs with higher clock rates.
** These recommendation are valid for FTP transfers with data compression disabled. If data compression is enabled, CPU requirements are notably higher. For best results, it is recommended to use CPU with as high performance per core as possible.
When Serv-U is deployed as a standalone server it is typically protected from the Internet by a single firewall. It may be connected to remote storage or remote authentication sources. All editions of Serv-U may be deployed in this architecture, but only Serv-U MFT Server may leverage external authentication sources.

The primary firewall supports FTP, FTPS (SSL/TLS), SFTP (SSH), HTTP, and/or HTTPS inbound connections from the Internet into Serv-U. This firewall may also be configured to allow outbound connections for support FTP/S active mode data connections, or may be “FTP aware” enough to open FTP data channels dynamically.
The Serv-U Gateway allows you to deploy Serv-U in a multi-tier architecture that meets or exceeds most managed file transfer (“MFT”) security requirements. This architecture allows you to:
Serv-U FTP Server* and Serv-U MFT Server may be deployed in this architecture, but Serv-U MFT Server should be used if you support SFTP (SSH) or HTTPS transfers or plan to leverage external authentication sources.

* Serv-U FTP Server does not support SFTP or HTTPS.
The firewall between the Internet and the DMZ segment supports FTP, FTPS (SSL/TLS), SFTP (SSH), HTTP, and/or HTTPS inbound connections from the Internet into Serv-U. This firewall may also be configured to allow outbound connections to support FTP/S active mode data connections, or may be “FTP aware” enough to open FTP data channels dynamically.
The firewall between the DMZ segment and the internal network only needs to allow outbound connections from Serv-U to Serv-U Gateway over TCP port 1180.
No active redundancy means the Serv-U server and Serv-U Gateway are single points of failure.
Serv-U can be deployed as a web farm of application servers to provide highly available (“HA”) services through horizontal scaling (a.k.a. “N+1”).
Serv-U MFT Server is the only Serv-U edition that support HA deployments because Serv-U’s HA configuration requires the use of external authentication sources. Up to five Serv-U servers are currently allowed in this configuration.

The primary firewall supports FTP, FTPS (SSL/TLS), SFTP (SSH), HTTP, and/or HTTPS inbound connections from the Internet into Serv-U. This firewall may also be configured to allow outbound connections to support FTP/S active mode data connections, or may be “FTP aware” enough to open FTP data channels dynamically.
A network load balancer must be used to distribute incoming connections to each Serv-U server.
Load balancers should be configured to preserve original IP addresses if you want to use Serv-U’s IP lockout protection. Load balancers should also use “sticky sessions” that lock all incoming connections from a particular IP address to a specific Serv-U server to allow FTP and FTPS connections to work properly.
All user home folders, virtual folders and other Serv-U folders must be configured to use remote storage (for example, NAS or file shares) rather than local hard drives. Serv-U must be able to make a CIFS (Windows networking) connection to those resources.
Serv-U can be deployed as a web farm of application servers to provide highly available (“HA”) services through horizontal scaling (a.k.a. “N+1”). It can also be deployed in a multi-tier architecture that meets or exceeds most managed file transfer (“MFT”) security requirements. Together, this sophisticated architecture allows you to:
Serv-U MFT Server is the only Serv-U edition that supports HA multi-tier deployments because Serv-U’s HA configuration requires the use of external authentication sources. Up to five Serv-U servers and three Serv-U Gateways are currently allowed in this configuration.

The primary firewall supports FTP, FTPS (SSL/TLS), SFTP (SSH), HTTP, and/or HTTPS inbound connections from the Internet into Serv-U. This firewall can also be configured to allow outbound connections to support FTP/S active mode data connections, or may be “FTP aware” enough to open FTP data channels dynamically.
The firewall between the DMZ segment and the internal network only needs to allow outbound connections from each of the Serv-U servers to each of the Serv-U Gateways over TCP port 1180.
A network load balancer must be used to distribute incoming connections to each Serv-U Gateway.
Load balancers should be configured to preserve original IP addresses if you want to use Serv-U’s IP lockout protection. Load balancers should also use “sticky sessions” that lock all incoming connections from a particular IP address to a specific Serv-U server to allow FTP and FTPS connections to work properly.
No load balancer is required between the Serv-U Gateway tier and the Serv-U server tier.
All user home folders, virtual folders and other Serv-U folders must be configured to use remote storage (for example, NAS or file shares) rather than local hard drives. Each Serv-U server must be able to make a CIFS (Windows networking) connection to those resources.
All Serv-U domains must use remote authentication provided by an ODBC-compliant database or Microsoft Active
Directory (AD).
Serv-U Gateway is able to act as a secure “reverse proxy” by avoiding direct connections from the Internet or the DMZ into the internal network. Behind the scenes, all inbound connections are served by Serv-U Gateway by tying them to outbound connections from the internally-based Serv-U server. This allows Serv-U Gateway to perform its duty without ever making an inbound connection from the DMZ segment to the trusted network.

1. When a Serv-U server starts up, it tries to connect to all its configured Serv-U Gateways. As it connects to each one, Serv-U provides specific instructions to each Serv-U Gateway about the protocols, IP addresses, and ports it should use to serve connections from the Internet. The connection Serv-U uses to provide this information is opened and reestablished as necessary so Serv-U Gateway can send messages back to Serv-U. This connection can be thought of as the “gateway control channel” or “GCC.”
2. When a file transfer client (for example, web browser, iPad, or FTP client) opens a connection to the Serv-U Gateway, the Serv-U Gateway will ask about the connection over the existing GCC. Serv-U performs any necessary IP checks and authentication against its own database or internal resources.
3. If Serv-U approves the incoming connection, Serv-U makes a new outbound connection from Serv-U to the Serv-U Gateway. This second connection can be thought of as the “gateway data channel” or “GDC.” If Serv-U denies the incoming connection Serv-U tells the Serv-U Gateway to deny the connection via the GCC and the Serv-U Gateway terminates the requesting client’s connection.
4. Serv-U Gateway stitches the original client connection and the GDC created for the approved connection together. From that point forward data transfer occurs between the client and Serv-U until either side terminates the session.
The Serv-U Administrator Guide describes how to set up domains, groups, user, and folders to support a Serv-U HA deployment. The following sections are particularly pertinent:
o Virtual Paths – Physical Path
o User Information – Home Directory
o Directory Access Rules – Access as Windows Users
o User Information – SSH Public Key Path
o Encryption – Configuring SSL for FTPS and HTTPS
o Encryption – SFTP (Secure File Transfer over SSH2)
o FTP Settings – Server Welcome Message sub
o FTP Settings – Message Files
o Serv-U Events – Execute Command Actions
o Configuring Domain Logs – Log File Path
o Domain Settings to set database-based or Active Directory authentication
o Serv-U Database Integration Guide for database-based authentication
o Serv-U Windows Groups for Active Directory authentication
The Serv-U Database Integration Guide contains detailed information and instructions to set up an authentication database in support of Serv-U web farms. Supported databases include SQL Server, Oracle Database, MySQL, PostgreSQL, and several other ODBC-compliant relational databases.